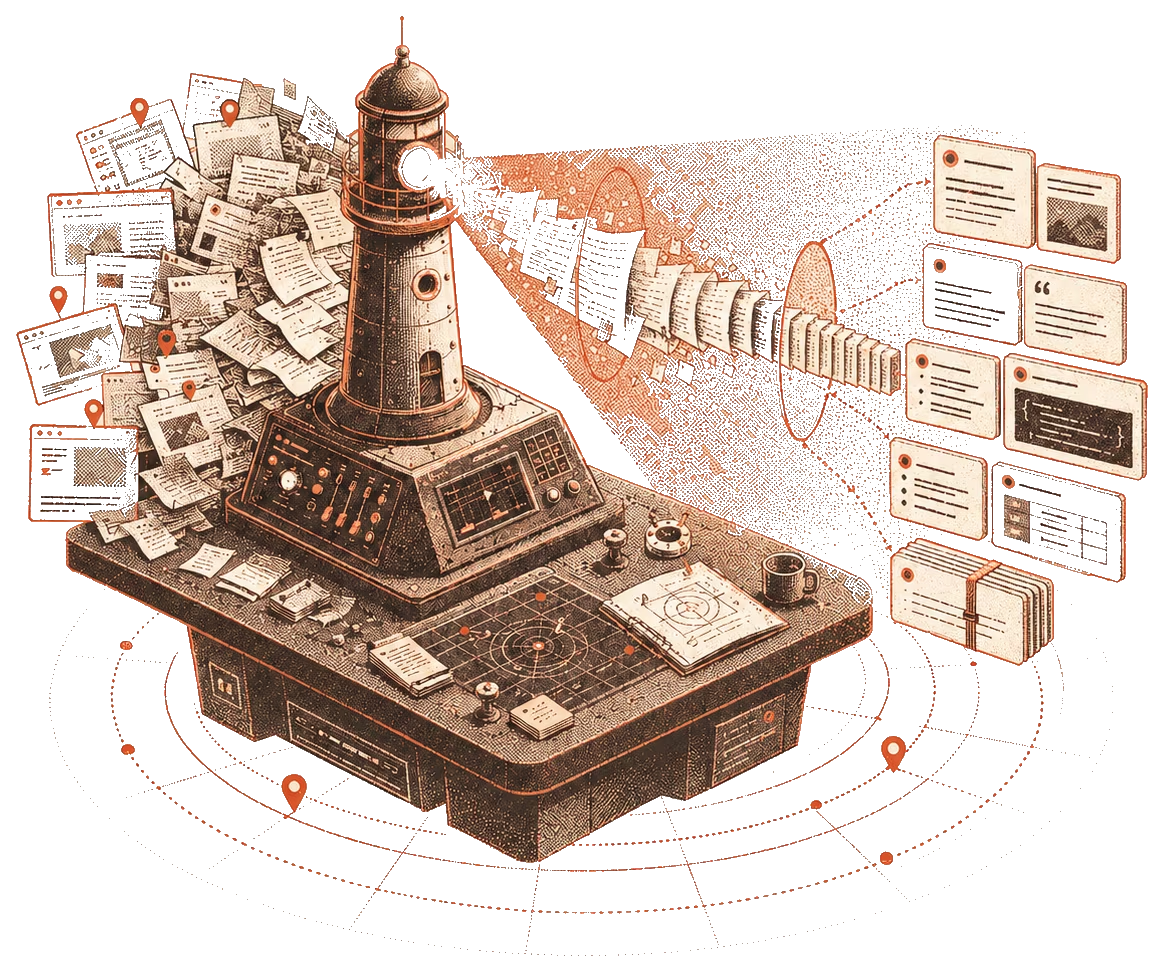
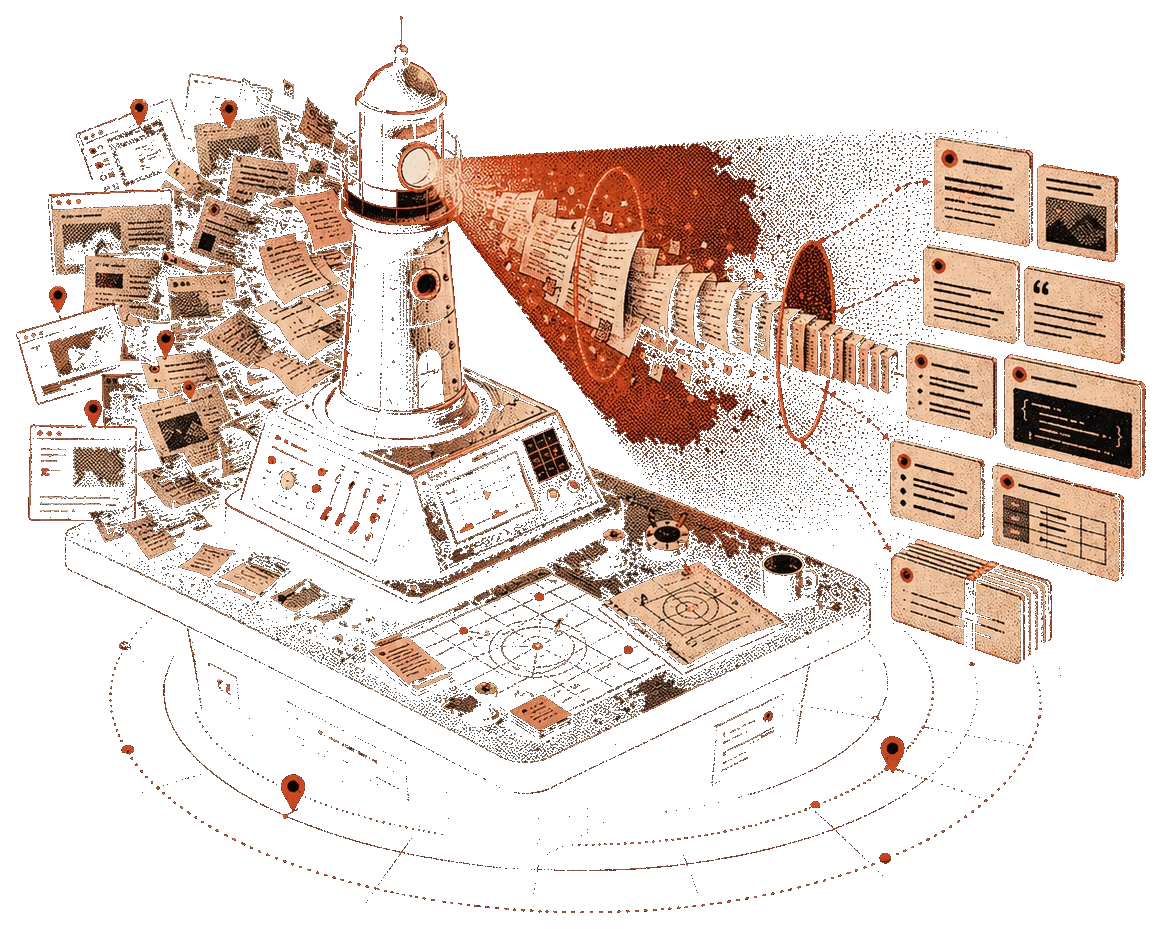
Most search APIs are judged by their index. This one is judged by its response object. It is built for agents and research pipelines rather than browsers, so the artifact that gets versioned and argued over is the shape of what comes back.
What a single response has to carry
An agent gets one response and decides from it. No second tab, no skimming, no instinct that a snippet is thin. Each result therefore keeps three things apart: where it came from, what was actually extracted, and how well the extraction went.
That separation is the contract. A caller can cite a source without parsing prose. It can drop weak results without inventing a heuristic. It can tell "nothing matched" apart from "the page refused the fetch", which are different problems with different next moves.
Markdown instead of HTML
The token saving comes mostly from one decision: return clean markdown, not raw HTML. Headings stay headings, lists stay lists, link targets survive. Navigation chrome, cookie banners and layout scaffolding do not.
Against the raw HTML of the same page, output lands roughly 70 percent smaller. That is the product, not a side effect. Context is the budget an agent spends, and a retrieval surface that costs less per call can be called more often.
Failing out loud
Silent confidence is the expensive failure mode. When a result is stale, partially extracted, or blocked at the source, the response says so in a field instead of emitting thin content that reads as complete. The caller routes around the gap rather than reasoning over it.
Underneath, several engines and social-native sources blend into one response shape. Callers integrate once and the routing layer decides where a query is best answered. Caching keeps repeat queries cheap enough for tight agent loops.
My part
- Designed the backend and infrastructure for the search API.
- Implemented clean markdown extraction, deep search, enrichment and token compression.
- Built the foundations for predictable response shape, source-aware results and production search workflows.
The API is live at sailorsearch.dev. One query and a look at the raw JSON is a faster review than anything on this page.